VisualBERT
VisualBERT represents a cutting-edge approach in the field of AI, combining vision and language processing. This model leverages Transformer layers to encapsulate rich representations from both textua
15,608
Votes
21,766
Views
11,810
Bookmarks
About
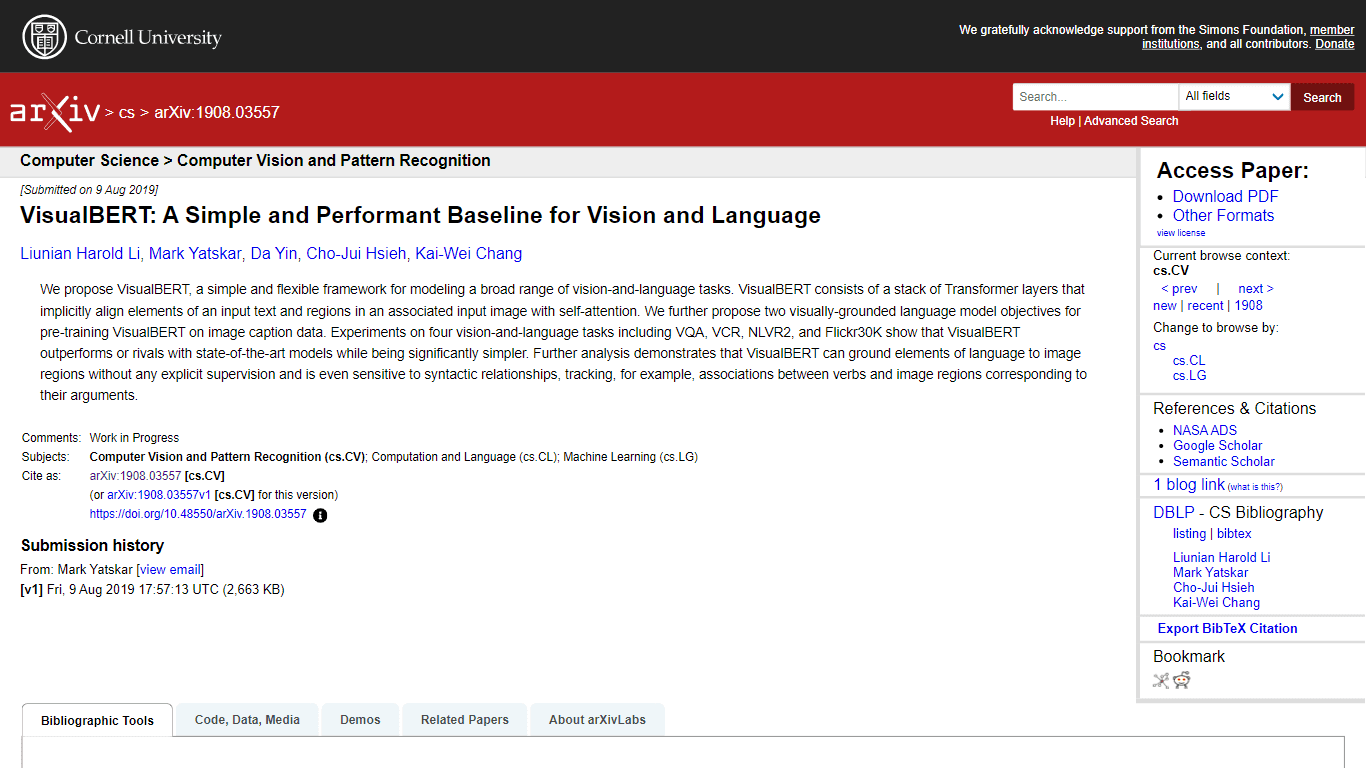
VisualBERT represents a cutting-edge approach in the field of AI, combining vision and language processing. This model leverages Transformer layers to encapsulate rich representations from both textual and visual inputs. It is pre-trained using image caption data with visually grounded language model objectives, enhancing its ability to comprehend and align elements in images with their linguistic descriptors. VisualBERT demonstrates noteworthy competencies in several vision-and-language tasks such as VQA (Visual Question Answering), VCR (Visual Commonsense Reasoning), NLVR2 (Natural Language Visual Reasoning for Real), and Flickr30K. Its performance is either on par or superior to other state-of-the-art models, yet maintains simplicity. One of VisualBERT's significant feats is its unsupervised grounding capability, which means it can associate words and phrases with corresponding image regions without direct instructional input, even discerning between syntactic relationships within the language component.
Key Features
- Transformer Layer Architecture: Utilizes stacked Transformer layers for implicit text and image region alignment.
- Visually-Grounded Pre-training Objectives: Employs image caption data to pre-train the model, enhancing contextual understanding.
- Performance on Vision-and-Language Tasks: Proven effectiveness in VQA, VCR, NLVR2, and Flickr30K tasks.
- Unsupervised Grounding Capability: Grounds linguistic elements to image regions without explicit supervision.
- Sensitivity to Syntactic Relationships: Identifies associations between language elements and image components, such as verbs to image regions.
FAQ
What is VisualBERT?
VisualBERT is a versatile framework for modeling a variety of vision-and-language tasks, based on a stack of Transformer layers and self-attention mechanisms.
What are some tasks VisualBERT excels in?
VisualBERT performs well in vision-and-language tasks, including VQA, VCR, NLVR2, and Flickr30K.
How does VisualBERT align language with image regions?
VisualBERT aligns elements of text with associated image regions using self-attention within its Transformer layers.
Can VisualBERT understand syntactic relationships in language?
Yes, VisualBERT can track syntactic relationships within the language, associating verbs with corresponding image regions, for example.
Does VisualBERT require explicit supervision to ground language to images?
No, VisualBERT can ground language elements to image regions without any explicit supervision.
You may also like
More tools in Other

WriteSmart
WriteSmart is an AI-powered tool that generates personalized and thoughtful comments to add value to conversations and build relationships on LinkedIn. With WriteSmart, you can boost engagement, warm

Postfluencer
Postfluencer is a cutting-edge online platform designed to empower individuals in enhancing their personal branding on Linkedin. With the capability to generate over 60,000 posts for users, Postfluenc
AI Img
aiimg.me is a comprehensive platform that integrates advanced AI imaging technologies to provide high-quality image generation, editing, and enhancement services. It allows users to create images from
Yepp AI
Yepp AI is an innovative platform that brings the power of artificial intelligence to marketing. With this platform, businesses can tap into the wealth of data they already have and leverage it throug
ICBINP | Civitai
Experience hyperrealistic image generation with ICBINP - "I Can't Believe It's Not Photography" - a powerful checkpoint for the Stable Diffusion model available on Civitai. The ICBINP LCM checkpoint i
MuseNet
MuseNet is a groundbreaking deep neural network that revolutionizes the way music is composed. With MuseNet, you have access to a powerful tool that can generate beautiful and intricate 4-minute music
Spikes Studio
Spikes helps creators extract captivating shorts from any video. Automatically get a title, description, hashtag recommendations, auto-captions, AI styling and quickly edit. Grow and give your audienc

SuperU AI
A nocode tool to create voice AI agents for customer communications.
ZAVATA
ZAVATA is revolutionizing the recruitment process with its sophisticated AI interview platform. With the motto "Automate Hiring with AI Interviewer," ZAVATA introduces a seamless hiring automation tha
Zeitpub
Zeitpub revolutionizes the publishing industry by offering an advanced AI writer that creates SEO-optimized and plagiarism-free content at an incredible pace. With just the click of a button, users ca

Verbacall
A platform that automatically answers, qualifies, and follows up on calls 24/7.

XLM
Discover the power of Cross-lingual Language Modeling with XLM, the original PyTorch implementation designed for pretraining language models that operate across multiple languages. XLM is a repository